Pre-Deploy to Production: Synthetic Monitoring for CI/CD Pipelines
Integrating synthetic monitoring for CI/CD pipelines prevents deployment regressions by executing deterministic, simulated user transactions against ephemeral preview environments, staging clusters, and canary deployments before changes reach your entire user base. By treating continuous synthetic tests as deployment gates rather than passive post-launch alarms, operations and engineering teams can automatically validate critical business transactions, API contracts, third-party webhooks, and edge routing rules at every step of the delivery lifecycle.
Why Unit and Integration Tests Miss Critical Production Regressions
Most modern delivery pipelines rely heavily on localized unit tests and mocked integration suites. While these tests are essential for validating discrete business logic and algorithmic correctness, they execute in artificial isolation. In a typical continuous integration (CI) run, external network calls are stubbed, database states are tightly bounded, and network topologies like reverse proxies, content delivery networks (CDNs), and cloud load balancers do not exist.
Consequently, critical production failures frequently slip past green test suites. A release may pass all unit tests with high code coverage while harboring fatal runtime defects caused by environmental discrepancies:
- CDN edge cache behaviors and header mutations: Mismatched
Cache-Controlheaders, droppedAuthorizationheaders at the edge, or incorrect cookie-forwarding policies can cause authentication to fail entirely in production while passing seamlessly in a local Docker container. - Transport Layer Security (TLS) and certificate mismatches: Ephemeral staging environments often bypass strict SSL/TLS handshake negotiations, domain name SNI checks, or cipher suite validations, masking runtime connection drops that will break client applications in production.
- External authentication handshakes: OAuth2 callbacks, OpenID Connect discovery endpoints, and magic-link redirects rely on real-world routing, public DNS propagation, and third-party API availability that mocked integration tests deliberately ignore.
- Database connection pool exhaustion and egress latency: Mocked databases do not expose the network latency or connection-throttling limits imposed by managed cloud databases when cold starts surge during traffic shifts.
The operational cost asymmetry between finding an error in a pre-merge pipeline step versus finding it in production is severe. Catching a broken authentication workflow during a pre-merge synthetic check takes minutes to fix: the pull request remains unmerged, zero customer transactions fail, and no incident triage is required. Conversely, triaging that same regression in production involves on-call escalations, customer support tickets, degraded availability metrics, emergency rollbacks, and potential post-incident reviews.
Core Architectural Patterns of Synthetic Monitoring for CI/CD Pipelines
Implementing synthetic monitoring for CI/CD pipelines requires a shift-left testing topology that evaluates live running infrastructure as code progresses through each environment. Rather than waiting for real user traffic to generate error metrics, synthetic monitors inject controlled, programmable transactions into the target environment.
The architecture consists of three functional layers across the deployment lifecycle:
- Targeted Probe Execution: Headless browser instances (such as Chromium runtimes) and programmatic API clients run synthetic scripts against ephemeral pull-request (PR) preview URLs, fixed staging domains, or canary-routed endpoints.
- Validation and Assertion Engine: The probe validates not only HTTP status codes (such as asserting
200 OKor201 Created), but also structural payload schemas, response latencies, DOM element render times, cookie creation, and asynchronous side effects (like database mutations or outbound emails). - Pipeline Control Gates: The synthetic runner communicates test outcomes back to the continuous delivery orchestrator via status checks, webhooks, or exit codes to determine whether to advance or abort the deployment.
Pipeline architects typically implement synthetic checks using one of two primary architectural patterns: synchronous blocking gates or asynchronous monitoring gates.
| Pattern | Execution Mechanism | Primary Use Case | Pipeline Impact | Failure Action |
|---|---|---|---|---|
| Synchronous Blocking Gate | CLI runner or blocking API probe invoked directly inside a CI job | Pre-merge PR branches, ephemeral preview stacks, pre-production staging | Blocks downstream deployment stages until all synthetic assertions pass | Halts pipeline; flags commit as failed; prevents deployment |
| Asynchronous Monitoring Gate | External monitoring probes executing continuously against rolling canary workloads | Canary deployments, blue-green cutovers, progressive traffic shifts | Runs concurrently alongside traffic routers without delaying the pipeline step | Triggers automated rollback webhooks or progressive delivery aborts |
To prevent false negatives and alert fatigue, your pipeline must enforce precise baseline performance and reliability metrics. A robust synthetic pipeline gate should measure three core vectors:
- Step-Level Latency Thresholds: Assert that critical endpoint responses remain within predefined p95 and p99 latency boundaries (e.g., login API responses must return under 450ms).
- Assertion Timeouts: Enforce strict timeouts on asynchronous UI state transitions and DOM hydrations to prevent hanging pipelines.
- Multi-Step Transaction Success Rates: Measure whether complete end-to-end user journeys (such as signup → email verification → workspace creation → billing setup) execute without an unhandled exception.
Implementing Pre-Production Synthetic Checks in Staging Environments
Running pre-production synthetic checks against ephemeral staging environments and feature branches ensures that code changes satisfy architectural and operational requirements prior to merging. Ephemeral preview environments—provisioned dynamically via Kubernetes namespaces, serverless preview deployments, or isolated container stacks—provide an ideal target for synthetic suites.
Step-by-Step Staging Synthetic Orchestration
A resilient pipeline workflow for pre-production validation follows this sequence:
- Environment Provisioning: The CI runner creates an isolated environment matching the PR branch, configuring DNS records or unique ingress routing rules (e.g.,
https://pr-412.preview.internal). - Database Seed & Isolation: Automated scripts seed the preview database with deterministic fixture data, provisioning dedicated synthetic test entities.
- Synthetic Execution Trigger: The CI runner invokes the synthetic suite via a command-line interface or webhook, passing dynamic environment variables (base URL, ephemeral auth tokens, and run IDs).
- Transaction Assertion: Synthetic probes execute the critical paths, capturing HAR (HTTP Archive) logs, network payloads, and execution traces.
- Teardown & Reporting: The synthetic runner reports status back to the CI system (such as GitHub Checks or GitLab Pipeline Status) and triggers test resource cleanup.
Managing Authenticated Synthetic Personas
Synthetic checks against modern web applications must navigate authentication layers without compromising production security posture. Storing long-lived, static administrative credentials inside CI configuration variables introduces credential leakage risks and breaks when sessions expire.
Instead, implement ephemeral authentication strategies:
- Signed Short-Lived JWT Generation: During test setup, generate short-lived JSON Web Tokens (JWTs) adhering to standard token formats such as the RFC 7519 specification using a dedicated, environment-scoped asymmetric signing key. This allows the synthetic probe to authenticate against API gateways without going through full third-party OAuth flows for every test step.
- Isolated Test-Tenant Credentials: Maintain isolated test tenants with restricted permissions that cannot access cross-tenant data or trigger live financial transactions.
- Automated Email and Magic-Link Flow Testing: Because modern applications rely heavily on passwordless authentication, synthetic checks must validate real email dispatch, delivery, and token consumption. Nightlamp runs synthetic checks, including magic-link and email-delivery flow monitoring via AgentDraft, ensuring that login links and critical transactional notices arrive within strict latency bounds. You can test your deliverability workflows using the magic link tester to verify token arrival latencies before shipping changes to production.
Testing complex transactional flows—such as webhook endpoints, external event listeners, and multi-tenant data ingestors—requires synthetic probes to simulate external client behaviors while validating downstream database state mutations. If your application relies on recurring background tasks, consult our guide on resolving issues when a scheduled job stopped running to understand how synthetic workers catch silent scheduling failures.
Monitoring Deployment Health During Canary and Blue-Green Rollouts
Deploying software through blue-green or canary release strategies minimizes risk by exposing only a small percentage of user traffic to the new release. However, relying solely on aggregated real-user monitoring (RUM) during a low-percentage canary rollout introduces a dangerous observability lag: if traffic is low, it may take hours for sufficient real-user errors to trigger an alert.
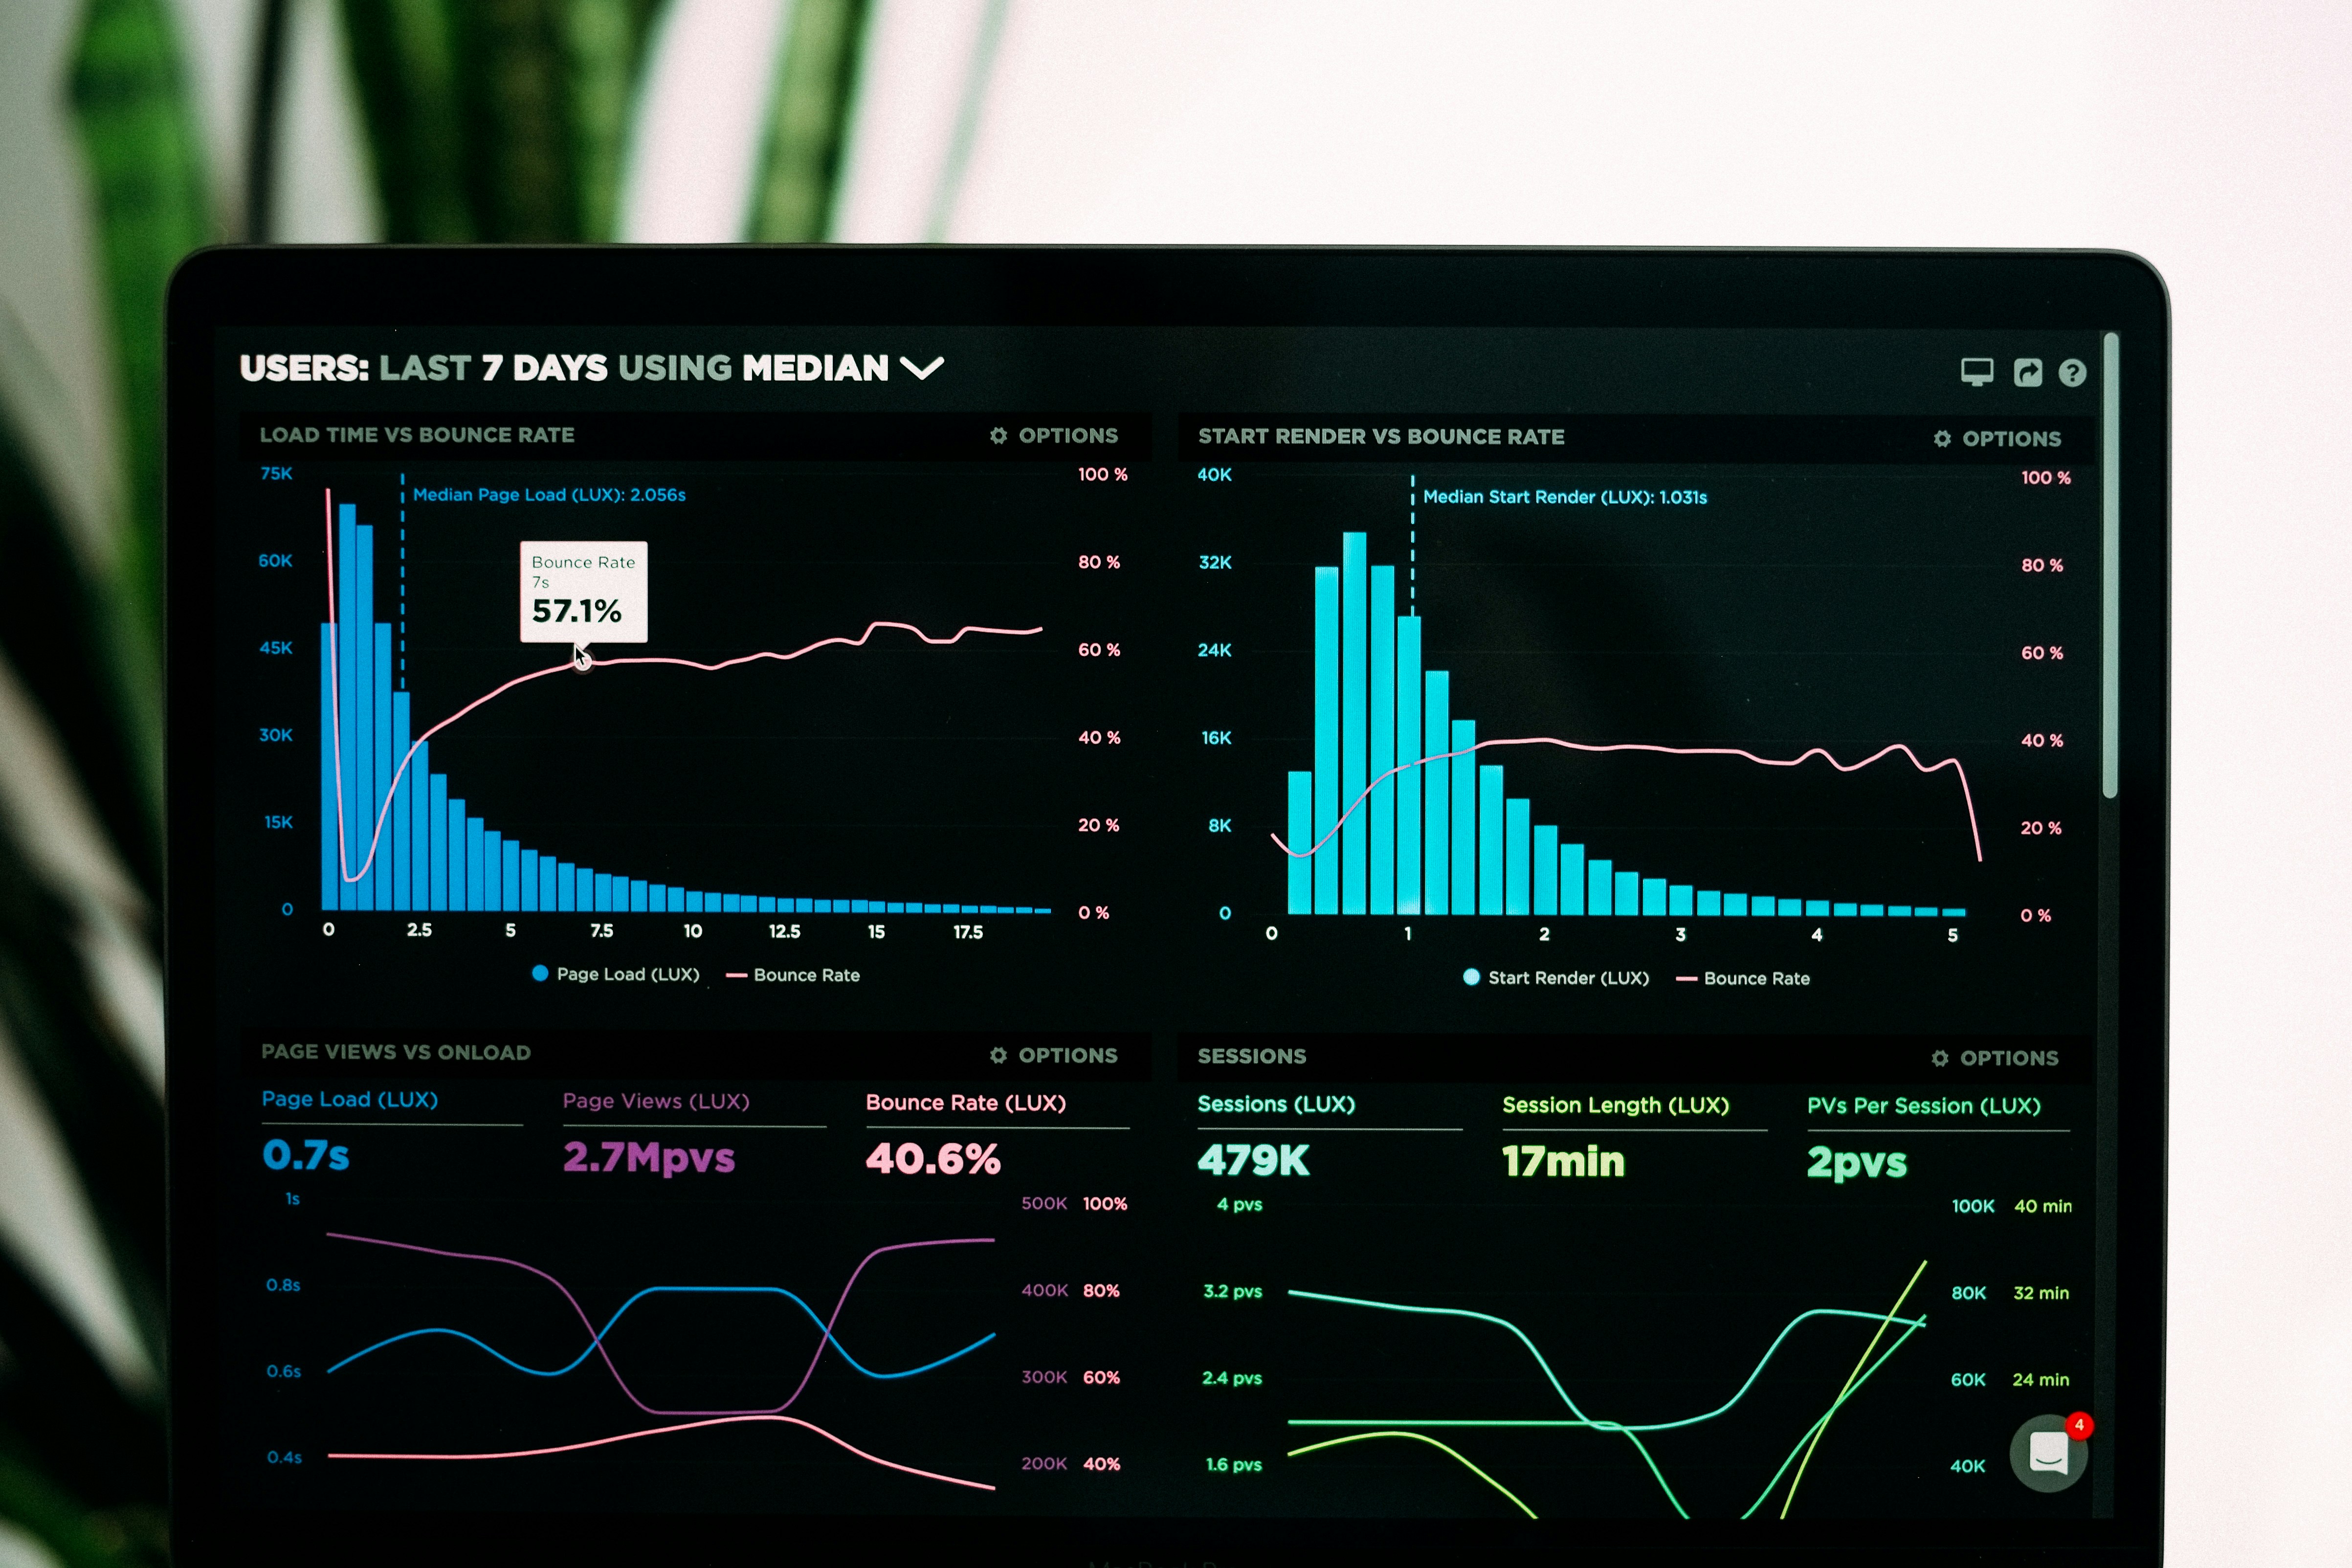
Using synthetic probes during canary traffic shifting enables active validation for monitoring deployment health within seconds of pod initialization, long before passive telemetry registers a statistically significant anomaly.
Targeting Canary Workloads Directly
To validate new code before shifting mainstream production traffic, configure synthetic probes to target canary pods directly. This is accomplished by setting specific routing headers, ingress annotations, or internal DNS records:
# Example: Executing a synthetic probe targeting a Canary release pod
curl -X POST https://api.yourcompany.com/v1/checkout/session \
  -H "Host: api.yourcompany.com" \
  -H "X-Canary-Route: canary" \
  -H "Authorization: Bearer ${SYNTHETIC_CANARY_TOKEN}" \
  -H "Content-Type: application/json" \
  -d '{
    "items": [{"sku": "SYNTH-TEST-ITEM", "quantity": 1}],
    "currency": "usd"
  }'
By inspecting the synthetic probe's response headers (such as X-Served-By: canary-v2-deployment-7f98b), the synthetic engine confirms that the probe reached the canary instance and asserts that HTTP response codes, payload schemas, and downstream telemetry match the expected contract.
Automating Progressive Rollout Gates
Continuous delivery operators, such as Argo Rollouts or Flagger, use metrics analysis templates to decide whether to advance canary traffic steps or trigger an immediate rollback. According to the Argo Rollouts Documentation, automated analysis runs can query external metric providers and synthetic test outcomes during traffic stepping phases to halt rollouts automatically if error rates breach predefined thresholds.
Here is an example declarative AnalysisTemplate in Kubernetes that queries synthetic health probe metrics during canary execution:
apiVersion: argoproj.io/v1alpha1
kind: AnalysisTemplate
metadata:
  name: synthetic-canary-gate
  namespace: production
spec:
  metrics:
  - name: synthetic-success-rate
    interval: 30s
    successCondition: result[0] >= 0.99
    failureLimit: 2
    provider:
      prometheus:
        address: http://prometheus-k8s.monitoring:9090
        query: |
          sum(rate(synthetic_check_success_total{environment="canary"}[2m]))
          /
          sum(rate(synthetic_check_executions_total{environment="canary"}[2m]))
This automated validation pattern provides deterministic verification that prevents broken revisions from receiving widespread production traffic.
Eliminating Flakiness in Automated Testing for Pipeline Reliability
The primary reason engineering teams disable or bypass synthetic gates in CI/CD pipelines is test flakiness. When a synthetic gate fails due to network jitter, cold starts, or timing issues rather than actual code defects, engineers lose confidence in the pipeline. Achieving reliable automated testing in deployment workflows requires systematic mitigation of non-deterministic failure modes.
Addressing Cold Starts and Asynchronous UI Rendering
In serverless runtimes and auto-scaled container clusters, the first request to an ephemeral or canary environment often encounters container cold starts, database connection pool initializations, or JIT compilation overhead. If synthetic monitors enforce a rigid 200ms latency assertion on the initial probe, false-positive pipeline failures will occur.
To eliminate cold-start false positives:
- Implement Pre-Warming Probes: Fire a non-blocking synthetic warm-up ping to wake serverless runtimes and establish database connection pools before executing transactional assertions.
- Use Explicit Condition Waiting: In headless browser synthetics, avoid arbitrary time sleeps (e.g.,
sleep(5000)). Instead, use deterministic DOM state locators that wait for explicit conditions, such aslocator.waitFor({ state: 'visible' })or network idle states. - Handle Hydration Lags: In modern single-page applications (SPAs), buttons may render visually before JavaScript event handlers attach. Synthetic scripts must assert that the application has completed client-side hydration before simulating click events.
Database State Isolation and Cleanup
Synthetic checks that perform write operations (such as creating customer accounts, submitting order forms, or updating profiles) can fail if subsequent runs encounter duplicate key constraints or polluted data states.
Implement strict state isolation strategies:
- Deterministic Unique Namespaces: Generate unique execution identifiers for each synthetic run (e.g.,
user_synth_${GITHUB_RUN_ID}_${TIMESTAMP}@example.com). - Transactional Teardown Hooks: Ensure synthetic test frameworks execute cleanup hooks in
finallyblocks to delete provisioned test records, regardless of whether the assertions passed or failed. - Tombstone Tagging: Mark synthetic records with metadata flags (such as
is_synthetic: true) to allow automated daily garbage-collection cron jobs to purge orphaned test entities from staging and production databases.
Retry Policies and Multi-Location Quorum
A single transient network packet loss between the CI probe runner and the staging cluster should rarely break a production deployment. Production-grade pipelines apply exponential backoff with jitter and quorum-based verification before failing a gate:
# Algorithm for robust synthetic gate retry
def execute_synthetic_gate(check_fn, max_retries=3, base_delay=2):
    for attempt in range(1, max_retries + 1):
        result = check_fn()
        if result.passed:
            return True
        if attempt < max_retries:
            sleep_time = (base_delay ** attempt) + random.uniform(0.1, 0.5)
            log.warn(f"Probe attempt {attempt} failed: {result.error}. Retrying in {sleep_time:.2f}s...")
            time.sleep(sleep_time)
    log.error(f"Synthetic gate failed after {max_retries} attempts.")
    return False
For globally distributed production canaries, synthetic probes should execute across multiple regional points of presence (PoPs). A failure must be confirmed across multiple geographic vantage points (a quorum check) to ensure the issue is an application regression rather than a localized Internet transit anomaly.
Integrating Synthetic Monitoring for CI/CD Pipelines into Modern GitOps
Treating synthetic tests as first-class software artifacts requires managing test definitions alongside application source code using infrastructure-as-code (IaC) principles. When synthetic assertions live in the same Git repository as the code they validate, updates to API schemas and UI flows can be submitted in the exact same pull request as the corresponding synthetic test updates.
Declarative Pipeline Integration with GitHub Actions
According to the GitHub Actions Documentation, workflow definitions can orchestrate multi-job testing matrices, manage artifact retention, and define explicit pipeline execution conditions. Below is a complete GitHub Actions workflow demonstrating how to execute a synchronous synthetic monitoring gate against an ephemeral preview deployment, publish test artifacts upon failure, and block merging if critical assertions fail:
name: Continuous Deployment & Synthetic Validation

on:
  pull_request:
    types: [opened, synchronize, reopened]
  push:
    branches: [main]

jobs:
  deploy-preview:
    runs-on: ubuntu-latest
    outputs:
      preview_url: ${{ steps.deploy.outputs.url }}
    steps:
      - name: Checkout Code
        uses: actions/checkout@v4

      - name: Deploy Ephemeral Stack
        id: deploy
        run: |
          echo "Deploying preview environment for commit ${{ github.sha }}..."
          # Deploy command emits unique URL
          PREVIEW_URL="https://pr-${{ github.event.pull_request.number }}.preview.internal"
          echo "url=${PREVIEW_URL}" >> $GITHUB_OUTPUT

  synthetic-gate:
    needs: deploy-preview
    runs-on: ubuntu-latest
    steps:
      - name: Checkout Synthetic Test Suite
        uses: actions/checkout@v4

      - name: Set up Node.js Runtime
        uses: actions/setup-node@v4
        with:
          node-version: '20'
          cache: 'npm'

      - name: Install Test Dependencies
        run: npm ci

      - name: Run Synthetic CI Suite
        env:
          TARGET_BASE_URL: ${{ needs.deploy-preview.outputs.preview_url }}
          SYNTHETIC_API_KEY: ${{ secrets.SYNTHETIC_API_KEY }}
          GIT_COMMIT_SHA: ${{ github.sha }}
        run: |
          npx synthetic-runner \
            --target="${TARGET_BASE_URL}" \
            --suite=ci-critical-path \
            --timeout=120000 \
            --retries=2 \
            --output=junit-report.xml

      - name: Upload Synthetic Diagnostics Artifacts
        if: failure()
        uses: actions/upload-artifact@v4
        with:
          name: synthetic-failure-artifacts
          path: |
            ./test-results/
            ./screenshots/
            ./network-traces/
Correlating Deployment Metadata with Availability Traces
To maintain observability across high-velocity deployment cycles, synthetic probe runs must be tagged with explicit build metadata:
git_commit_sha: The exact Git commit hash being evaluated.deployment_id: The unique identifier generated by the continuous delivery pipeline.environment_tier: The target environment (e.g.,preview,staging,canary, orproduction).pipeline_trigger: The initiating event (e.g.,pr_merge,scheduled_cron,tag_release).
When synthetic probe results are annotated with these deployment tags, operations teams can instantly correlate availability dips or latency spikes with specific code releases, drastically reducing the Mean Time to Identify (MTTI) regressions. Review our documentation on alert rules to see how to structure deterministic notification thresholds based on deployment tags.
Diagnosing Pipeline Regressions: Where Human Triage Outperforms Alert Floods
While automated synthetic gates excel at detecting deployment failures, interpreting the raw diagnostic data during an active incident remains a complex operational challenge. A failed synthetic assertion can result from multiple distinct root causes: a breaking backend database migration, a third-party payment gateway outage, a misconfigured CORS header, or a stale DNS cache record.
Automated continuous delivery tooling often responds to synthetic failures by emitting generic error codes or flooding on-call Slack channels with uncontextualized stack traces. When engineers receive a barrage of disconnected notifications during a deployment, valuable minutes are lost determining whether the root cause is a transient infrastructure issue or a critical software defect.
Human engineers diagnose incidents for you; Nightlamp does not just fire alerts. When a synthetic check flags a broken transaction, having experienced operations specialists triage the failure logs, inspect the HTTP headers, and isolate the failure domain ensures that your engineering team receives precise, actionable remediation guidance rather than raw noise.
To maintain clear architectural boundaries, keep in mind that Nightlamp is managed monitoring and diagnostics for your app's availability and delivery, not an APM or distributed-tracing platform. Furthermore, Nightlamp does not auto-remediate infrastructure on its own; a real engineer diagnoses each incident and tells you exactly what to fix. For organizations seeking reliable production assurance, Nightlamp is a paid managed service (a $279/mo Priority tier is available), not an open-source or free-forever tool. Review the available options on our pricing page to see how dedicated diagnostic support integrates into your continuous delivery lifecycle.
Establishing an Effective CI Failure Handoff Protocol
To streamline the handoff between automated pipeline failures and human triage teams, enforce these structural logging practices within your synthetic runners:
- Capture Complete Network HAR Files: Log all request headers, response headers, and payload structures for every synthetic step leading up to the failure.
- Record Step-by-Step DOM Snapshots: Capture visual screenshots and accessibility tree dumps at the exact moment an assertion fails.
- Extract Edge Tracing Headers: Preserve unique distributed trace IDs conforming to the W3C Trace Context specification (such as
traceparent,X-Request-ID, orCF-Ray) to correlate the synthetic probe with backend server logs.
Frequently Asked Questions
How does synthetic monitoring in CI/CD differ from end-to-end testing with Playwright or Cypress?
While end-to-end (E2E) testing frameworks like Playwright or Cypress often execute the same underlying browser automation commands, synthetic monitoring in CI/CD applies those scripts against live, fully deployed infrastructure across environments with continuous assertion thresholds. Traditional E2E tests run once during the build step against localized or mock-heavy runners and focus primarily on functional correctness. In contrast, synthetic CI/CD monitoring evaluates real network routing, TLS negotiations, external API latencies, CDN behaviors, and deployment health over time, serving as both a deployment gate and an ongoing availability monitor.
Can synthetic checks in deployment pipelines cause data pollution in production databases?
Yes, if not properly isolated. Synthetic checks that perform create, update, or delete (CUD) operations can clutter analytics, skew inventory counts, or trigger real billing events. To prevent data pollution, synthetic checks should use deterministic tenant identifiers (such as dedicated test accounts), inject mocking flags into external gateways (like Stripe test-mode tokens), and utilize automated teardown hooks or tombstone tags that allow automated daily jobs to purge synthetic records.
How do pre-production synthetic checks handle third-party service dependencies like Stripe or OAuth providers?
Pre-production synthetic checks should avoid hitting live third-party production APIs for destructive actions. Instead, use dedicated sandbox or test-mode credentials (such as Stripe test API keys) within staging and preview environments. For third-party identity providers, synthetic suites can authenticate via staging OAuth applications or leverage signed ephemeral JWT tokens issued specifically for automated test suites to bypass interactive multi-factor authentication challenges safely.
What is the best way to handle synthetic authentication without hardcoding static API keys in CI/CD?
Hardcoding static credentials in pipeline definitions creates security and operational risks. The best approach is to generate short-lived, dynamically signed tokens (such as OIDC-federated credentials or asymmetric JWTs) during the pipeline setup phase. For browser-based UI journeys, synthetic runners can query secure secret managers (such as AWS Secrets Manager or HashiCorp Vault) at runtime to retrieve time-bounded credentials that rotate automatically.
Sign up for Nightlamp to monitor critical authentication and transactional flows across your environments with dedicated human engineer incident diagnostics.